5 abril, 2024
Autors:
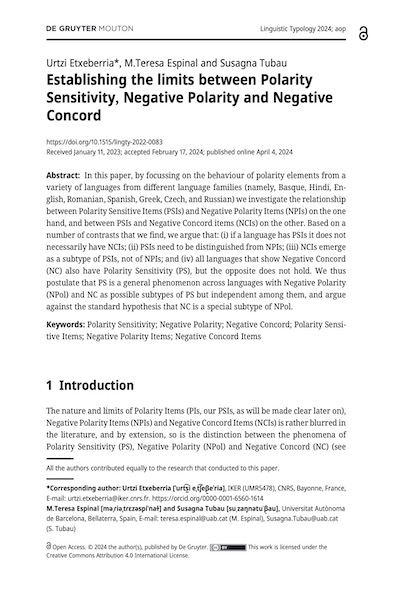
Urtzi Etxeberria, M.Teresa Espinal & Susagna Tubau
Títol:
Establishing the limits between Polarity Sensitivity, Negative Polarity and Negative ConcordEditorial: Linguistic Typology (de Gruyter)
Data de publicació: 4 d'abril del 2024
Text completIn this paper, by focussing on the behaviour of polarity elements from a variety of languages from different language families (namely, Basque, Hindi, English, Romanian, Spanish, Greek, Czech, and Russian) we investigate the relationship between Polarity Sensitive Items (PSIs) and Negative Polarity Items (NPIs) on the one hand, and between PSIs and Negative Concord items (NCIs) on the other. Based on a number of contrasts that we find, we argue that: (i) if a language has PSIs it does not necessarily have NCIs; (ii) PSIs need to be distinguished from NPIs; (iii) NCIs emerge as a subtype of PSIs, not of NPIs; and (iv) all languages that show Negative Concord (NC) also have Polarity Sensitivity (PS), but the opposite does not hold. We thus postulate that PS is a general phenomenon across languages with Negative Polarity (NPol) and NC as possible subtypes of PS but independent among them, and argue against the standard hypothesis that NC is a special subtype of NPol.
3 octubre, 2024
Autors:
Gemma Repiso-Puigdelliura
Títol:
Preferential use of full glottal stops in vowel-initial glottalization in child speech: Evidence from novel wordsEditorial: Journal of Child Language (Cambridge University Press)
Data de publicació: 3 d'octubre 2024
Text completVowel-initial glottalization constitutes a cue to prosodic prominence, realized on a strength continuum from creaky phonation to complete glottal stops. While there is considerable research on children’s early utilization of acoustic cues for stress marking, less is understood about the specific implementation of vowel-initial glottalization in American English. Eight sequences of function + novel words were elicited from groups of 5-to-8-year-olds, 8-to-11-year-olds, and adults. Children exhibit a similar rate of prevocalic glottalization to adults but differ in its phonetic implementation, producing a higher rate of glottal stops compared to creaky phonation with respect to adults.
17 setembre, 2020
Autors:
Javier Fernández Sánchez & Dennis Ott
Títol:
DislocationsEditorial: Language and Linguistics Compass, Vol.14 issue 9 (John Wiley & Sons Ltd)
Data de publicació: Setembre 2020
Text completDislocation is a kind of construction in which a phrasal constituent (the dislocate) appears at the outer left or right edge of a gap-less clause (its host) that contains a pronominal correlate of the dislocate. Dislocations are widely attested and presumably universally available across languages. The construction raises a number of problems for core assumptions of syntactic theory, in that these assumptions appear to thwart any coherent resolution of the question of how the dislocate relates to the internal structure of its host. This contribution is divided into two parts. In Part 1, we review central empirical properties of dislocation, which, taken together, appear to defy the laws of syntax as commonly assumed. In Part 2, we review key proposals that have emerged over the last decennia to resolve this paradox and restore dislocations to normalcy.
19 abril, 2024
Autors:
Evelina Leivada, Vittoria Dentella & Fritz Günther
Títol:
Biolinguistics, vol.18Editorial: PsychOpen
Data de publicació: 19 abril, 2024
Text completWe identify and analyze three caveats that may arise when analyzing the linguistic abilities of Large Language Models. The problem of unlicensed generalizations refers to the danger of interpreting performance in one task as predictive of the models’ overall capabilities, based on the assumption that because a specific task performance is indicative of certain underlying capabilities in humans, the same association holds for models. The human-like paradox refers to the problem of lacking human comparisons, while at the same time attributing human-like abilities to the models. Last, the problem of double standards refers to the use of tasks and methodologies that either cannot be applied to humans or they are evaluated differently in models vs. humans. While we recognize the impressive linguistic abilities of LLMs, we conclude that specific claims about the models’ human-likeness in the grammatical domain are premature.
26 agost, 2024
Autors:
Evelina Leivada, Fritz Günther & Vittoria Dentella
Títol:
Reply to Hu et al: Applying different evaluation standards to humans vs. Large Language Models overestimates AI performanceEditorial: PNAS 121(36), e2406752121 (National Academy of Sciences)
Data de publicació: 26 d'agost, 2024
Text completDentella et al. (DGL) argued that 3 Large Language Models (LLMs) perform almost at chance in grammaticality judgment tasks, while revealing an absence of response stability (1). Hu et al.’s (HEA) “re-evaluation” led to different conclusions (2). HEA argue that i) “LLMs align with human judgments on key grammatical constructions,” ii) LLMs show “human-like grammatical generalization capabilities,” while iii) grammaticality judgments (GJs) are not the best evaluation method because they “systematically underestimate” these capabilities. While HEA’s aim to elucidate the abilities of LLMs is laudable, their claims are fraught with interpretative difficulties.